1.3 The CUDA platform
CUDA 平台不仅包含 GPU 硬件本身,还包括 NVIDIA Driver、CUDA Toolkit、CUDA Runtime、PTX、GPU Binary 等一整套软硬件组件和技术。这一节的重点是理解这些组件之间的关系,以及 CUDA 程序最终如何从高级语言转换为可以在具体 GPU 上执行的机器代码。与前面的 Programming Model 一样,这些概念并不依赖某一种具体编程语言。
CUDA Platform 可以从整体上理解为一套连接 CUDA Application 与 NVIDIA GPU Hardware 的完整软硬件体系:
CUDA Application
       ↓
CUDA Runtime API
       ↓
CUDA Driver API
       ↓
NVIDIA Driver
       ↓
NVIDIA GPU
GPU 本身通过 Compute Capability 描述其支持的架构功能,例如 CC 12.0 对应 sm_120。CUDA Toolkit 提供开发 CUDA 程序所需的 Compiler、Libraries、Headers 和分析工具,而 NVIDIA Driver 是所有 GPU 操作的底层基础软件。
从代码生成角度,CUDA 的核心链路则可以概括为:
CUDA C++ / DSL
       ↓
PTX
Virtual ISA
compute_xx
       ↓
Cubin
Native GPU Binary
sm_xx
       ↓
GPU
Cubin 是针对具体 GPU 架构生成的 Native Binary,可以直接执行但 Binary Compatibility 有一定架构限制;PTX 是 Virtual ISA,可以在运行时通过 Driver JIT 编译成具体 GPU Binary,从而提供面向未来 GPU 的 Forward Compatibility。多个架构版本的 cubin 和 PTX 可以一起存储在 Fatbin 中,使同一个 CUDA Application 能够支持多代 GPU。
因此,这一节最核心的关系可以记成:
CC 12.0        → GPU Capability
sm_120         → Physical GPU / Binary Target
compute_120    → PTX Virtual Target

CUDA Toolkit   → 开发 CUDA 程序
CUDA Runtime   → 高层 CUDA API
NVIDIA Driver  → 控制 GPU + Driver API + JIT
PTX            → Virtual ISA
cubin          → Native GPU Binary
fatbin         → 多个 GPU Code 的容器
1.3.1 Compute Capability and Streaming Multiprocessor Versions
每一款 NVIDIA GPU 都有一个 Compute Capability(CC,计算能力) 版本号,用于描述该 GPU 支持哪些硬件特性以及部分硬件参数。Compute Capability 使用 X.Y 的形式表示,其中 X 是 Major Version,Y 是 Minor Version,例如:
Compute Capability 12.0
        ↓
Major = 12
Minor = 0
Compute Capability 与 GPU 中 SM 的版本直接对应。例如:
CC 12.0
   ↓
SM Version
   ↓
sm_120
因此,CC 12.0 是从 GPU 能力角度描述架构,而 sm_120 通常用于表示针对该 SM 架构生成的 GPU Binary。不同 Compute Capability 支持的功能和硬件参数可以在 Technical Appendices 中查询。
1.3.2 CUDA Toolkit and NVIDIA Driver
NVIDIA Driver 可以理解为 GPU 的底层系统软件,是使用 NVIDIA GPU 所必需的基础组件。无论是 CUDA Computing、图形显示,还是 Vulkan、Direct3D 等其他 GPU API,最终都需要 NVIDIA Driver 与 GPU 硬件交互。Driver 使用类似 r580 这样的版本号。
CUDA Toolkit 则是一套用于开发 GPU Computing 软件的工具集合,其中包括:
Libraries
Headers
Compiler / Tools
Profiling & Analysis Tools
...
CUDA Toolkit 和 NVIDIA Driver 是两个独立的软件产品。
CUDA Toolkit 中一个非常重要的组件是 CUDA Runtime。CUDA Runtime 提供 CUDA Runtime API 和相关语言扩展,负责完成 CUDA 编程中的常见操作,例如:
Memory Allocation
Data Copy
Kernel Launch
Device Management
...
因此可以简单理解为:
CUDA Application
       ↓
CUDA Runtime
       ↓
NVIDIA Driver
       ↓
NVIDIA GPU
CUDA Toolkit、NVIDIA Driver 和不同 GPU 架构之间存在相应的 Compatibility Rules,具体兼容关系由 CUDA Compatibility 文档定义。
1.3.2.1 CUDA Runtime API and CUDA Driver API
CUDA 提供两套主要 API:
CUDA Runtime API
CUDA Driver API
其中 CUDA Driver API 是 NVIDIA Driver 直接提供的底层 API,而 CUDA Runtime API 构建在 Driver API 之上,为开发者提供更加方便的高级接口。
其关系可以理解为:
Application
     ↓
CUDA Runtime API
     ↓
CUDA Driver API
     ↓
NVIDIA Driver
     ↓
GPU
CUDA Programming Guide 主要使用 Runtime API,因为它更加方便,能够完成绝大多数 CUDA 编程任务;但原则上 Runtime API 提供的大多数能力都可以直接通过 Driver API 实现,同时还有一些功能只能通过 Driver API 使用。一个应用也可以同时使用 Runtime API 和 Driver API。
1.3.3 Parallel Thread Execution (PTX)
CUDA 平台中非常重要但很多时候对开发者不可见的一层是 PTX(Parallel Thread Execution)。
PTX 是 NVIDIA GPU 的一种 Virtual Instruction Set Architecture(虚拟指令集),同时可以看作一种面向 NVIDIA GPU 的高级 Assembly Language。它位于高级程序和具体 GPU Physical ISA 之间,提供了一层与具体硬件架构相对解耦的抽象。
典型的编译过程可以理解为:
CUDA C++ / DSL / High-Level Language
                ↓
               PTX
                ↓
       Physical GPU Binary
                ↓
               GPU
开发者理论上可以直接编写 PTX,但通常没有必要。更常见的方式是让 Compiler 或 Triton 等 DSL 自动生成 PTX,再由 NVIDIA 的 Compiler 或 Driver 将 PTX 编译成具体 GPU 可以运行的 Binary。正因为存在 PTX 这一中间层,CUDA 平台并不局限于 NVIDIA 官方直接支持的编程语言,其他语言和 DSL 也可以以 PTX 作为中间表示接入 CUDA 平台。
PTX 本身也有版本,并与 Compute Capability 对应。例如:
Compute Capability 8.0
        ↓
PTX Target
        ↓
compute_80
这里需要特别区分两个以后经常出现的名字:
compute_80 → PTX / Virtual Architecture

sm_80      → GPU Binary / Real Architecture
1.3.4 Cubins and Fatbins
CUDA 程序通常使用 C++ 等高级语言编写。Device Code 首先可以被编译成 PTX,然后进一步编译为针对某一种具体 GPU 架构的真实二进制代码,这种 CUDA GPU Binary 称为 cubin。
例如:
CUDA C++
   ↓
PTX
compute_120
   ↓
GPU Binary
sm_120
   ↓
cubin
一个 cubin 针对具体的 SM Version,因此针对 sm_120 编译得到的 cubin 包含可以直接在对应架构 GPU 上执行的机器代码。
一个 CUDA Application 通常同时包含:
CPU Code
+
GPU Code
其中 GPU Code 会被存放在一个称为 Fatbin(Fat Binary) 的容器中。Fatbin 可以同时包含多个不同架构的 cubin,也可以包含 PTX。程序运行时,CUDA 会根据当前 GPU 选择最合适的 GPU Code。
例如一个 Fatbin 可以包含:
Application Binary
│
├── CPU Binary
│
└── Fatbin
     │
     ├── cubin: sm_80
     ├── cubin: sm_86
     ├── cubin: sm_90
     │
     └── PTX: compute_80
这样同一个 Application Binary 就可以支持多种不同 GPU 架构。
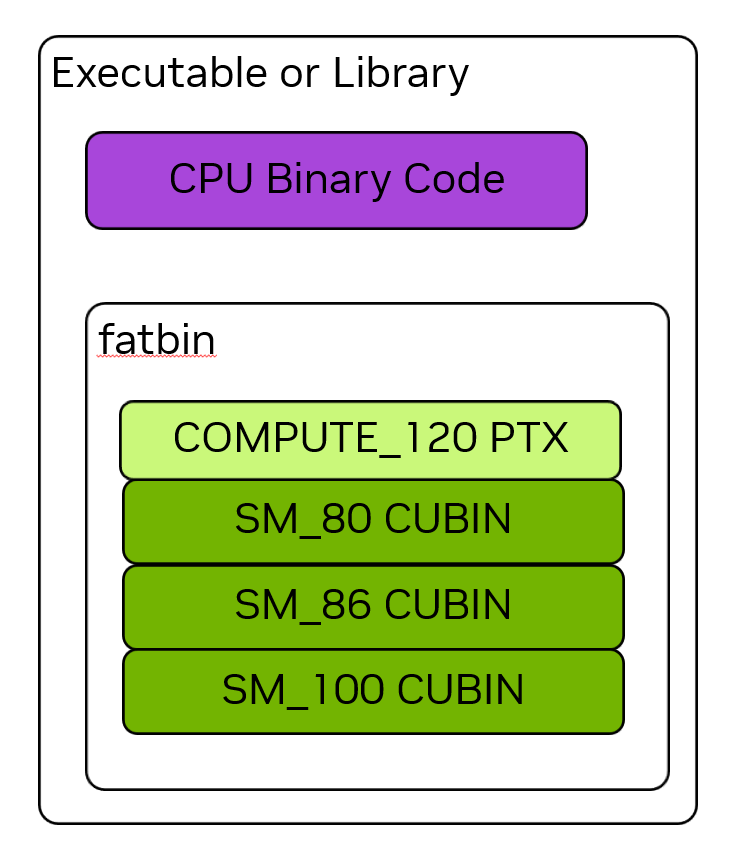
图10:可执行文件或库的二进制文件同时包含 CPU 二进制代码以及用于 GPU 代码的 fatbin 容器。fatbin 可同时包含 cubin GPU 二进制代码和 PTX 虚拟 ISA 代码。PTX 代码可针对未来目标进行 JIT 编译。
1.3.4.1 Binary Compatibility
Cubin 是针对具体 SM Version 生成的 Binary,因此它的兼容性受到 Compute Capability 限制。
在相同 Major Compute Capability 中,较高 Minor Version 的 GPU 可以运行针对较低或相同 Minor Version 编译的 cubin。例如:
sm_86 cubin

✓ CC 8.6 GPU
✓ CC 8.9 GPU
✗ CC 8.0 GPU
因为:
8.9 ≥ 8.6
8.0 < 8.6
但是不同 Major Compute Capability 之间并不保证 Binary Compatibility,例如:
sm_86
  ✗
CC 9.0 GPU
因此:
Cubin 的 Binary Compatibility 主要存在于相同 Major Compute Capability 内,并要求目标 GPU 的 Minor Version 不低于 Binary Target。
这些兼容性保证只适用于由 nvcc 等 NVIDIA 官方工具生成且没有被修改的 GPU Binary。
1.3.4.2 PTX Compatibility
与 cubin 不同,PTX 提供的是 Forward Compatibility。
如果一个应用中保存了:
compute_80 PTX
那么它可以在运行时通过 JIT Compiler 针对 Compute Capability 8.0 或更高版本的 GPU 生成对应 Binary,例如:
compute_80 PTX
       ↓
      JIT
       ↓
sm_120 Binary
因此,即使某块 GPU 在应用编译时还不存在,只要程序中保留了兼容的 PTX,未来的 Driver 仍然可以针对新 GPU 将其编译为可执行 Binary。
这就是 PTX 在 CUDA 中非常重要的作用之一:
Cubin
→ Native Binary
→ 直接执行
→ 架构兼容范围有限

PTX
→ Virtual ISA
→ Runtime JIT
→ 提供 Forward Compatibility
1.3.4.3 Just-in-Time Compilation
当应用运行时加载 PTX,NVIDIA Driver 会负责将 PTX 编译成当前 GPU 可以直接执行的 Binary,这个过程称为:
JIT(Just-in-Time Compilation)。
完整过程可以理解为:
PTX
 ↓
NVIDIA Driver
 ↓
JIT Compiler
 ↓
Current GPU Binary
 ↓
GPU Execution
JIT 的代价是第一次运行时需要额外的编译时间,因此会增加 Application Loading Time;但它也带来两个重要好处:应用可以运行在编译时尚未出现的新 GPU 上,同时可以利用新版 NVIDIA Driver 中更新的 JIT Compiler 优化。
为了避免每次启动程序都重新编译,Driver 会把 JIT 生成的 Binary 保存在 Compute Cache 中。之后再次运行程序时可以直接使用缓存结果。当 NVIDIA Driver 升级后,Compute Cache 会自动失效,从而让应用重新使用新版 Driver 中的 JIT Compiler 生成 Binary。
除了使用 nvcc 在应用构建阶段编译 CUDA C++,CUDA 还提供 NVRTC(NVIDIA Runtime Compilation),允许应用在运行过程中动态把 CUDA C++ Device Code 编译成 PTX。